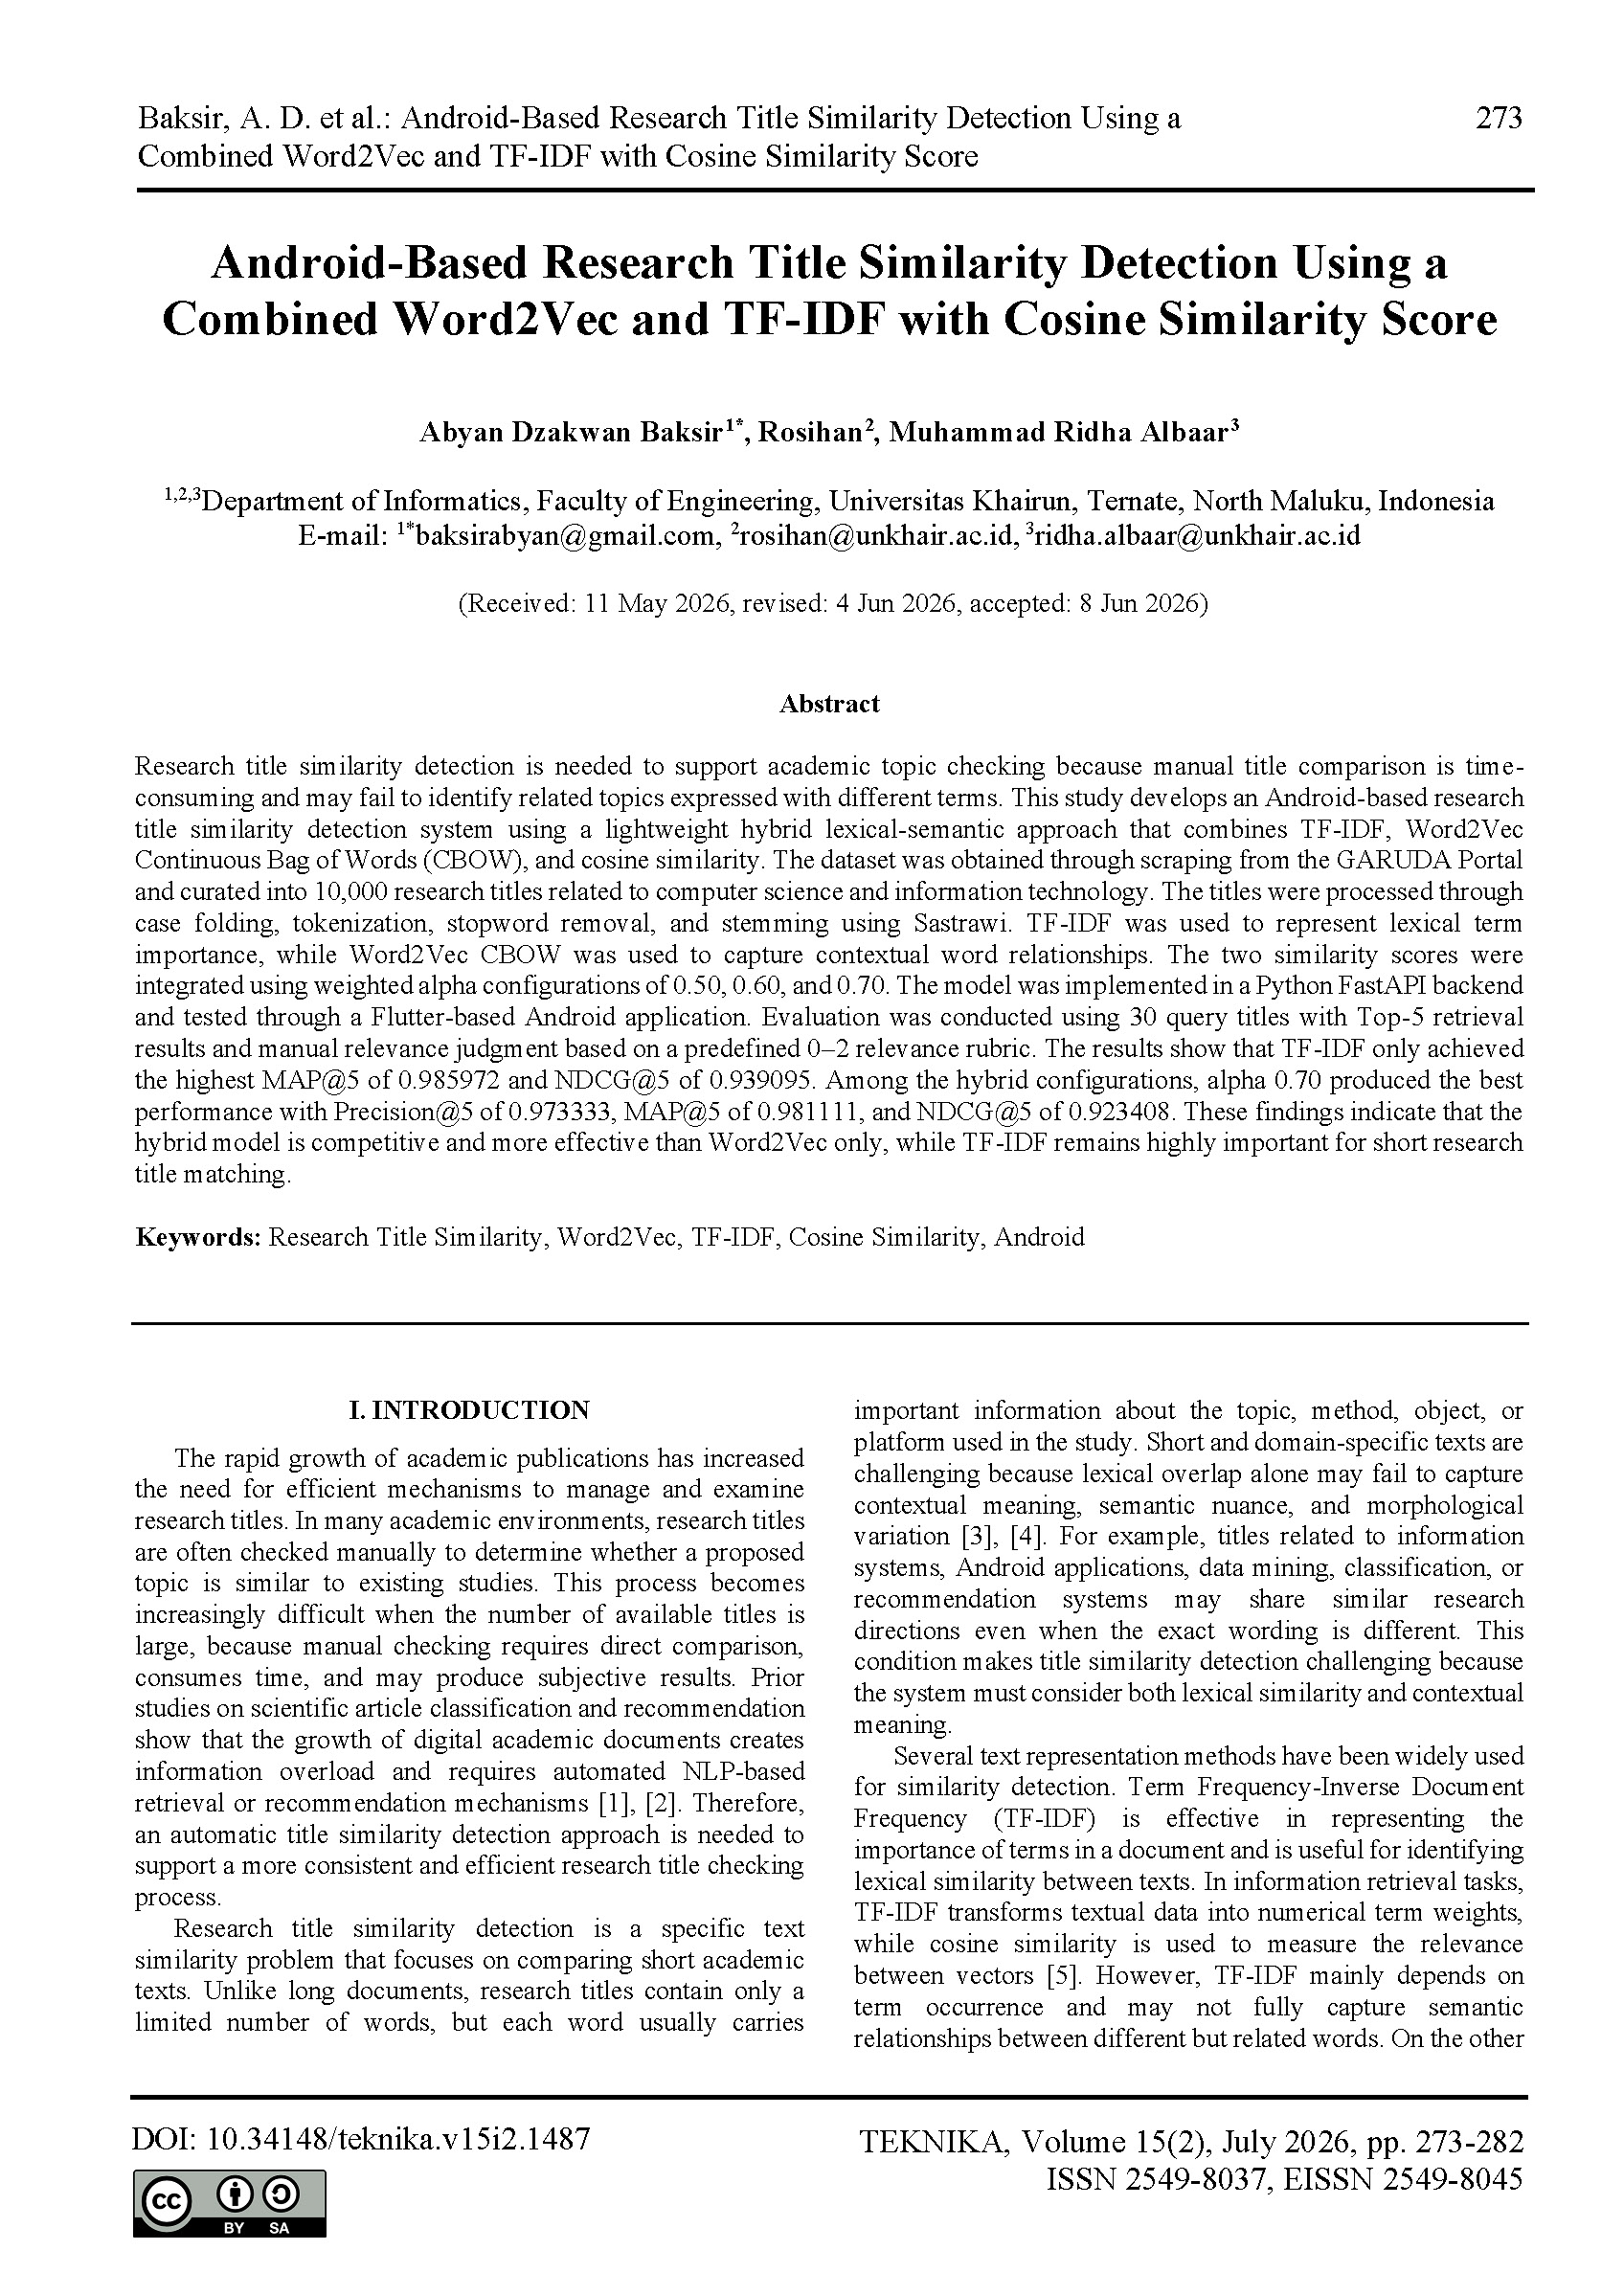
Android-Based Research Title Similarity Detection Using a Combined Word2Vec and TF-IDF with Cosine Similarity Score
DOI:
https://doi.org/10.34148/teknika.v15i2.1487Keywords:
Research Title Similarity, Word2Vec, TF-IDF, Cosine Similarity, AndroidAbstract
Research title similarity detection is needed to support academic topic checking because manual title comparison is time-consuming and may fail to identify related topics expressed with different terms. This study develops an Android-based research title similarity detection system using a lightweight hybrid lexical-semantic approach that combines TF-IDF, Word2Vec Continuous Bag of Words (CBOW), and cosine similarity. The dataset was obtained through scraping from the GARUDA Portal and curated into 10,000 research titles related to computer science and information technology. The titles were processed through case folding, tokenization, stopword removal, and stemming using Sastrawi. TF-IDF was used to represent lexical term importance, while Word2Vec CBOW was used to capture contextual word relationships. The two similarity scores were integrated using weighted alpha configurations of 0.50, 0.60, and 0.70. The model was implemented in a Python FastAPI backend and tested through a Flutter-based Android application. Evaluation was conducted using 30 query titles with Top-5 retrieval results and manual relevance judgment based on a predefined 0–2 relevance rubric. The results show that TF-IDF only achieved the highest MAP@5 of 0.985972 and NDCG@5 of 0.939095. Among the hybrid configurations, alpha 0.70 produced the best performance with Precision@5 of 0.973333, MAP@5 of 0.981111, and NDCG@5 of 0.923408. These findings indicate that the hybrid model is competitive and more effective than Word2Vec only, while TF-IDF remains highly important for short research title matching.
Downloads
References
[1] S. Rahman, H. K. Shanto, U. A. Koana, and S. M. Danish, “Automated Research Article Classification and Recommendation Using NLP and Machine Learning,” in 2025 3rd International Conference on Foundation and Large Language Models (FLLM), 2025, pp. 837–844, doi: 10.1109/FLLM67465.2025.11391003.
[2] E. W. Pratomo and E. Utami, “Hybrid TF-IDF and Embedding Model for Improving Similarity and Clustering Accuracy,” JOINTECS (Journal of Information Technology and Computer Science), vol. 10, no. 1, pp. 33–40, 2025, doi: 10.31328/jointecs.v10i1.7344.
[3] Tukino, E. Sediyono, H. Hendry, A. Hananto, E. Novalia, and F. Nurapriani, “Evaluation of Word2Vec and FastText Models for Text Similarity Measurement Assessment,” BIS Information Technology and Computer Science, vol. 3, article V326007, 2026, doi: 10.31603/bistycs.485.
[4] H. Hendry, T. Tukino, E. Sediyono, A. Fauzi, and B. Huda, “HyEWCos: A Comparative Study of Hybrid Embedding and Weighting Techniques for Text Similarity in Short Subjective Educational Text,” Information, vol. 16, no. 11, Art. no. 995, pp. 1–28, 2025, doi: 10.3390/info16110995.
[5] W. Tanuwijaya, C. E. Setiawan, H. Irsyad, and A. Rahman, “Implementasi TF-IDF dan Cosine Similarity untuk Penyaringan Dokumen Berita Program Makan Siang Gratis Pemerintah Indonesia,” DEVICE: Journal of Information System, Computer Science and Information Technology, vol. 6, no. 2, pp. 322–334, 2025, doi: 10.46576/device.v6i2.6724.
[6] S.-V. Oprea, A. Bâra, and M. P. Cristescu, “A Comprehensive Analysis of Text Similarity Metrics and Vectorization Techniques for Content-Based Product Recommendation,” IEEE Access, vol. 14, pp. 58670–58689, 2026, doi: 10.1109/ACCESS.2026.3683598.
[7] E. Aprianto, D. Mahdiana, and A. Wibowo, “Optimizing Bag of Words and Word2Vec with Vocabulary Pruning and TF-IDF Weighted Embeddings for Accurate Chatbot Responses in Indonesian Treasury Services,” Jurnal Teknik Informatika (JUTIF), vol. 7, no. 1, pp. 587–605, 2026, doi: 10.52436/1.jutif.2026.7.1.5370.
[8] Sutriawan, S. Rustad, G. F. Shidik, and Pujiono, “Performance Evaluation of Text Embedding Models for Ambiguity Classification in Indonesian News Corpus: A Comparative Study of TF-IDF, Word2Vec, FastText BERT, and GPT,” Ingénierie des Systèmes d’Information, vol. 30, no. 6, pp. 1469–1482, 2025, doi: 10.18280/isi.300606.
[9] J. Lu, “Text vectorization in sentiment analysis: A comparative study of TF-IDF and Word2Vec from Amazon Fine Food Reviews,” ITM Web of Conferences, vol. 70, article 03001, pp. 1–11, 2025, doi: 10.1051/itmconf/20257003001.
[10] C. Neves-Moutinho and M. F. Arámburo-Castell, “Literature Summary Based on TF-IDF with Term-Term Correlation Matrix Analysis,” Research in Computing Science, vol. 154, no. 10, pp. 99–109, 2025.
[11] X. Feng, “Web Crawling Algorithm Fusing TF-IDF and Word2Vec Feature Extraction,” Journal of Web Engineering, vol. 24, no. 5, pp. 713–738, 2025, doi: 10.13052/jwe1540-9589.2452.
[12] L. A. Utami, H. Rachmi, and S. Hidayatulloh, “A Hybrid TF-IDF and Knowledge Graph-Enhanced Retrieval-Augmented Generation Framework with Large Language Models for Domain-Aware Question Answering,” Journal of Applied Data Sciences, vol. 7, no. 2, pp. 866–881, 2026, doi: 10.47738/jads.v7i2.1136.
[13] M. W. J. Rahmatullah and A. Purnama, “Applying NLP and Cosine Similarity in the Preliminary Selection Process of Recruitment Systems,” Bit-Tech (Binary Digital - Technology), vol. 8, no. 2, pp. 2565–2576, 2025, doi: 10.32877/bt.v8i2.3287.
[14] F. Azzahra, B. Irawan, A. Faqih, D. Pratama, and D. A. Kurnia, “Comparison of TF-IDF and Word2Vec Feature Representations for Emotion Classification of Tokopedia E-Commerce Review Using LinearSVC,” Journal of Artificial Intelligence and Engineering Applications (JAIEA), vol. 5, no. 2, pp. 3466–3471, 2026, doi: 10.59934/jaiea.v5i2.2215.
[15] A. G. Sinaga, Robet, and O. Pribadi, “Comprehensive Comparison of TF-IDF and Word2Vec in Product Sentiment Classification Using Machine Learning Models,” Journal of Applied Informatics and Computing (JAIC), vol. 10, no. 1, pp. 184–191, 2026, doi: 10.30871/jaic.v10i1.11582.
Downloads
Published
Issue
Section
License
Copyright (c) 2026 Teknika

This work is licensed under a Creative Commons Attribution-ShareAlike 4.0 International License.